Hi, I'm Abreham

I'm an AI & LLM engineer building production-minded systems — agents, RAG, observability, MCP infrastructure, and resource-efficient language models.

About

I build AI systems end to end — from retrieval and agent orchestration to evaluation, observability, tool interfaces, and developer workflows. My recent work focuses on production-minded LLM applications, multimodal agents, MCP infrastructure, and resource-efficient language models.

I like taking ambiguous problems, turning them into working systems, and then making the systems easier to inspect, evaluate, and improve.

Research

From LLaMA to DeepSeek Multi-head Latent Attention with Knowledge Distillation: Making InkubaLM Fast and Efficient

Early research

Redesigning InkubaLM's attention architecture (LLaMA → DeepSeek MLA) for fast on-device inference while preserving its low-resource language knowledge through distillation.

LLMModel ArchitectureMLAKnowledge DistillationEdge AILow-Resource Languages
Read more

InkubaLM-0.4B is a small language model developed by Lelapa AI's Fundamental Research Team for low-resource African languages. It is built on a LLaMA-based architecture with approximately 0.4B parameters, designed to make useful language technology accessible under limited compute and data constraints. This is independent research I do because I care about low-resource languages.

My current research direction is to investigate whether InkubaLM's attention architecture can be redesigned around DeepSeek's Multi-head Latent Attention (MLA) to reduce inference overhead and make the model more practical for on-device deployment. DeepSeek introduced MLA as a mechanism for compressing the key-value representation, reducing the memory cost of the KV cache during inference.

Rather than simply fine-tuning the existing model, I am exploring rebuilding the modified architecture from scratch and studying how to transfer the capabilities of the original InkubaLM into the new architecture through knowledge distillation. The objective is to preserve as much of the original model's linguistic knowledge as possible while delivering a more inference-efficient architecture that can run efficiently on phones and other local, resource-constrained hardware.

At this stage, this is early research: I am primarily reading the relevant literature, studying the InkubaLM architecture and DeepSeek's attention mechanism, and experimenting with how the two approaches could be combined. The long-term goal is to contribute an African-language model that can run efficiently on phones and other local, resource-constrained hardware.
LLM-Powered Android Keyboard

Early research

On-device language model for contextual next-word prediction.

Mobile AIOn-Device InferenceNLPAndroidLLMEdge Computing
Read more

I am also experimenting with an Android keyboard powered by a small language model for next-word prediction. The goal is to investigate whether an LLM can provide useful contextual predictions directly on a mobile device while working within the constraints of mobile compute, memory, latency, and battery usage.

The project is currently in the early experimental stage. I am exploring different model and inference configurations, studying the hardware constraints of phones, and investigating how much language-model capability can be delivered locally without requiring a large cloud-based model.

A major part of this work is understanding the trade-off between prediction quality, model size, inference latency, and on-device resource usage. The longer-term direction is to build a practical local language-prediction system that can operate efficiently on Android hardware.

Open Source

Agenta AI — Contributor

Contributed fixes and improvements to Agenta, an open-source platform for building agents and automations.

Towards AI Academy — Course Reviewer

Reviewed Agent Engineering course material, suggesting code fixes and content improvements.

What I build in production and research

Selected Project Work

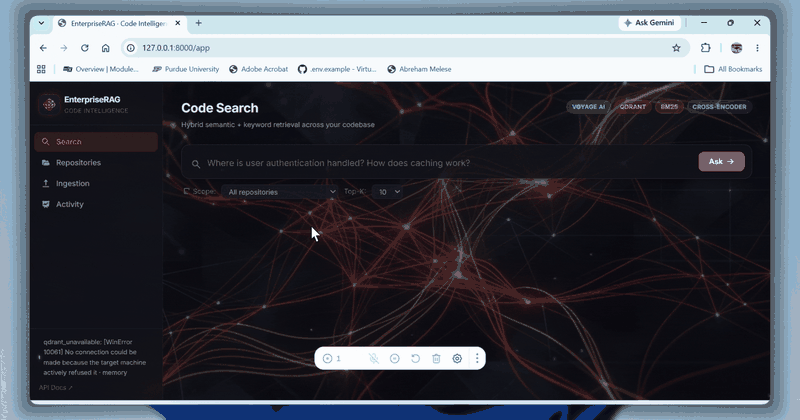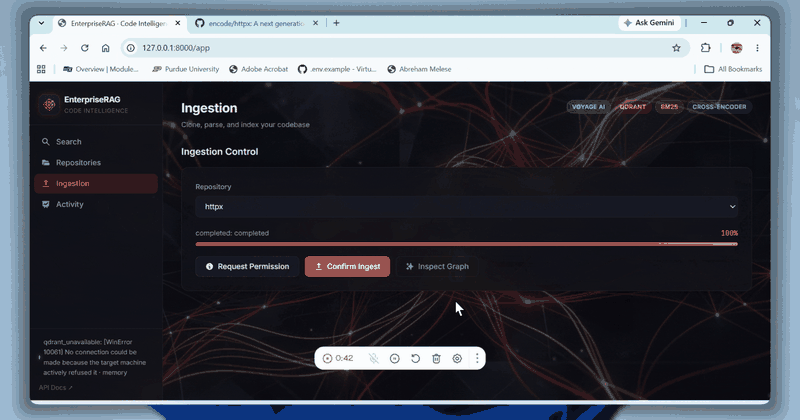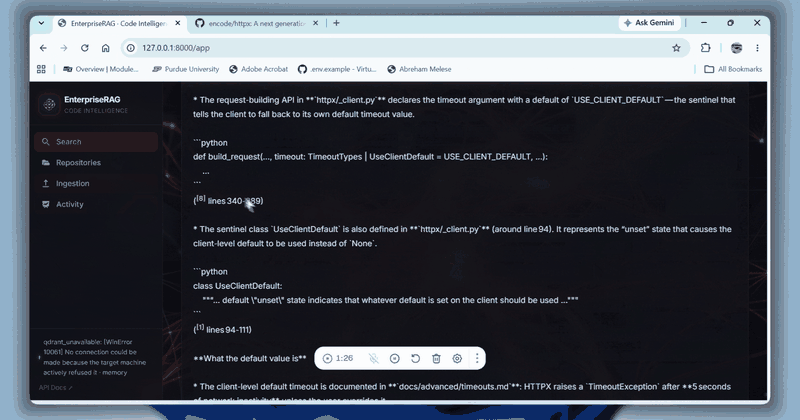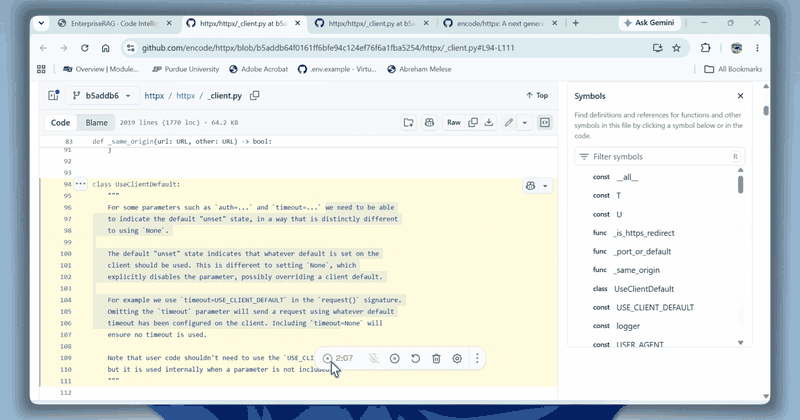
EnterpriseRAG

EnterpriseRAG

Cross-repository code intelligence for engineering teams.

PythonFastAPILangGraphTree-sitter
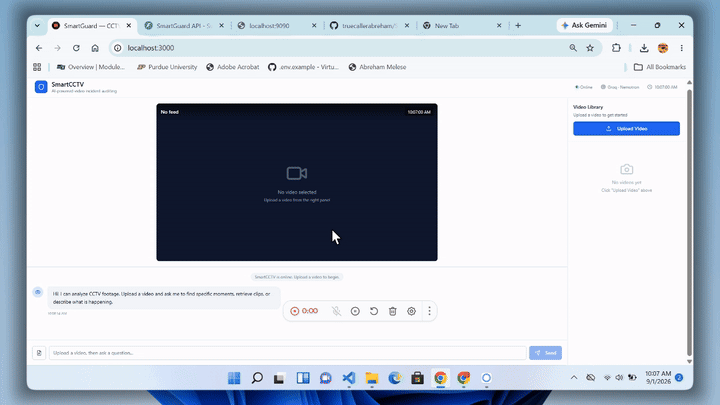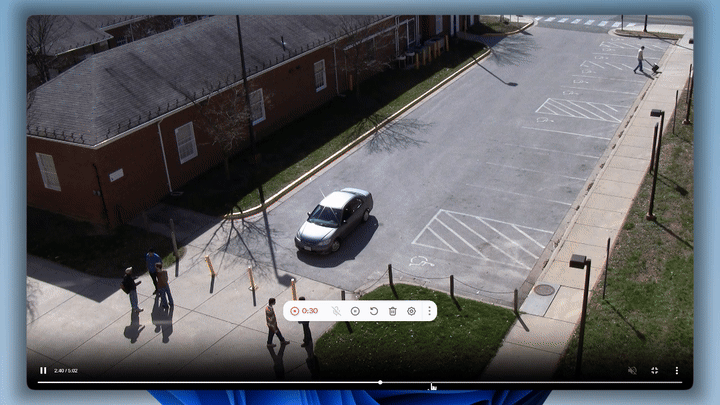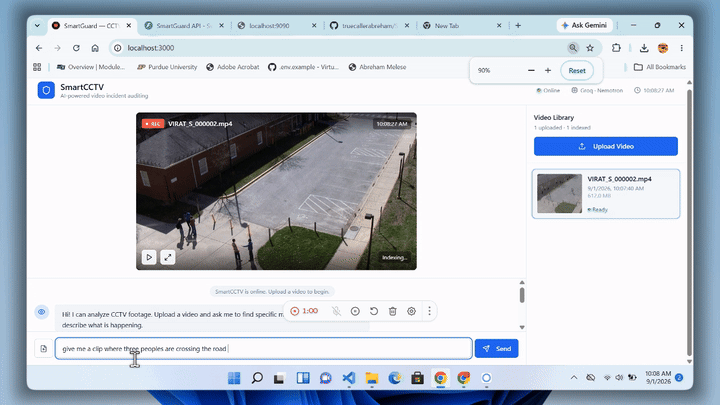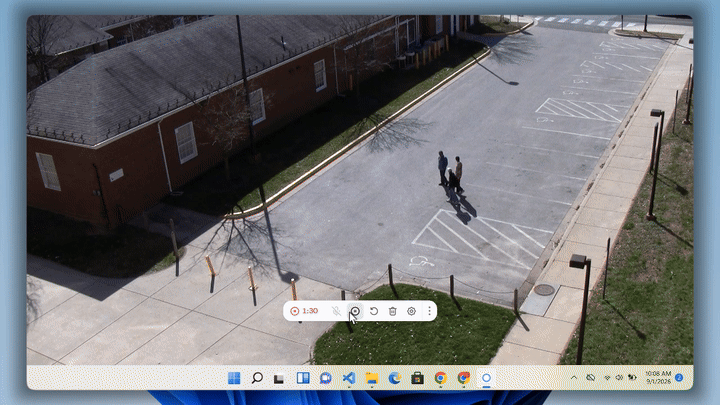
SmartGuard

SmartGuard

A multimodal incident-auditing agent for transit CCTV footage.

Multimodal AIVLMMCPFastAPI
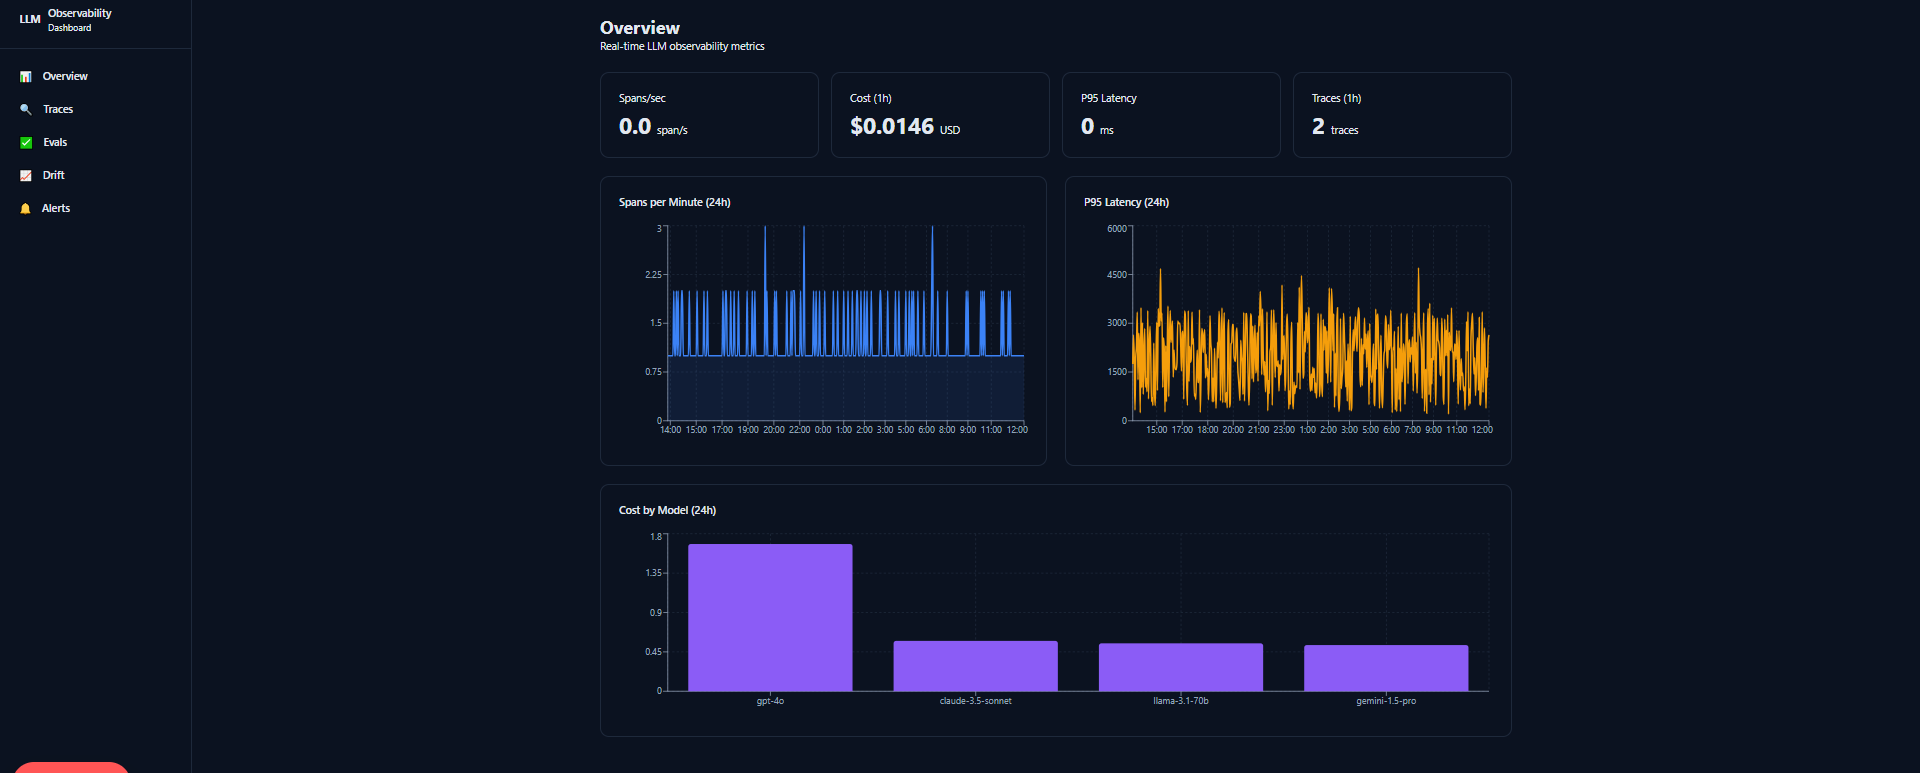
LLM Observability & Eval Dashboard

LLM Observability & Eval Dashboard

A self-hosted stack for monitoring LLM applications after deployment.

OpenTelemetryLLM EvalsDeepEvalRAGAS
Arc - Architecture Canvas

Arc - Architecture Canvas

A developer tool for architectural discovery and design.

TypeScriptReactReact FlowCLI

Get in Touch

Want to discuss AI systems, collaboration, or research? The best way to reach me is by email at xvimelese@gmail.com. You can also find me on GitHub and LinkedIn.